IBM’s Krishna puts open models at a tenth of the cost but sees a skills gap
Open-weight models now deliver 90% of frontier performance at 10–25% of the token cost, IBM’s chief executive told analysts. By his own account, few companies have the engineers to run them
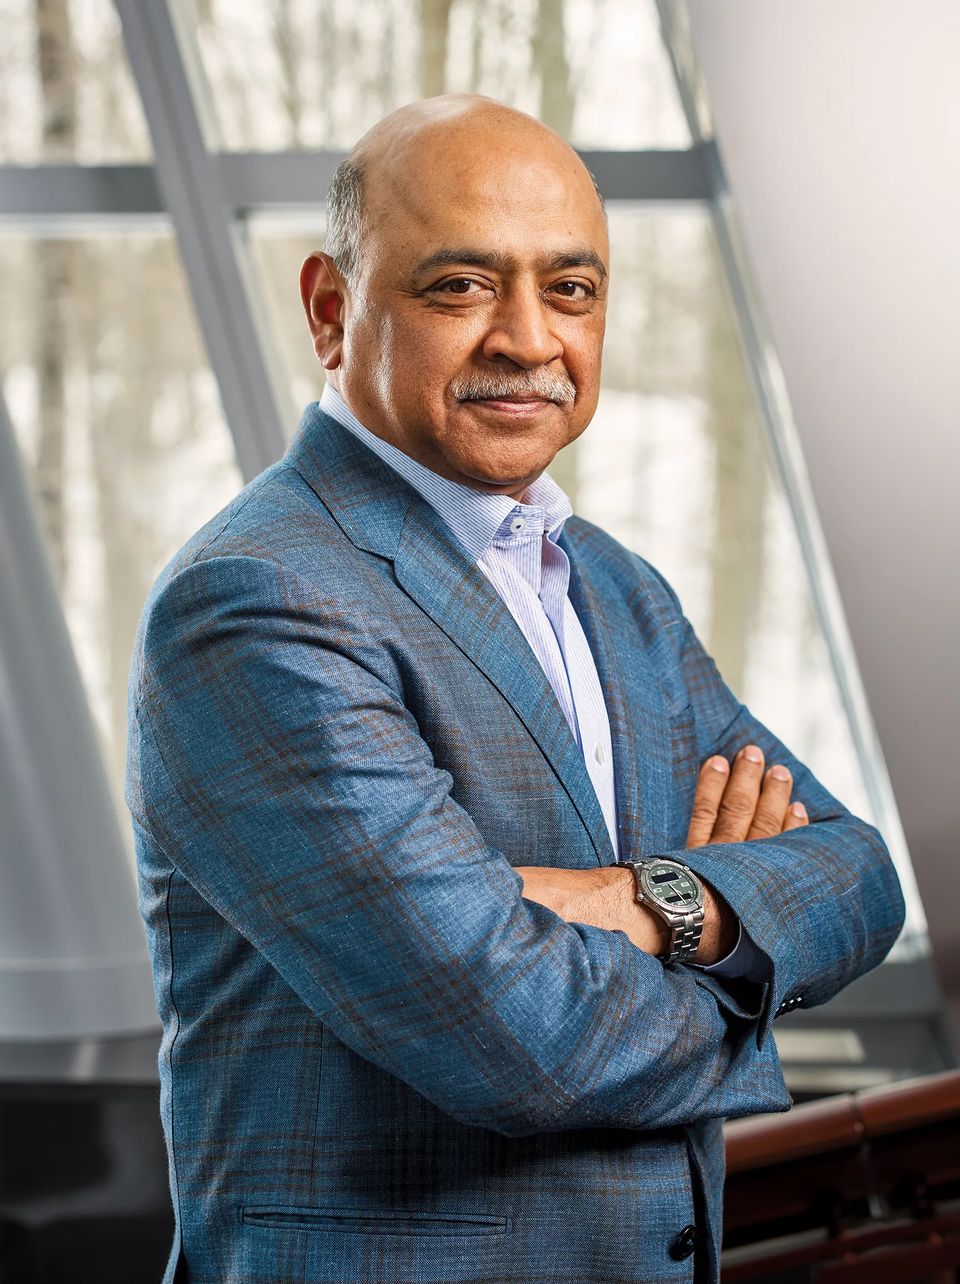
Arvind Krishna, IBM’s chief executive, closed the company’s third-quarter earnings call on 21 October with a pricing case against frontier AI models. Open-weight models, he told analysts, now run at “anywhere from 25% to 10% of the token cost of the frontier models” and are “90% as effective”.
“Would you like something that’s 10% of the cost if it’s 90% as good as the best, or do you want to pay that 10 times higher cost?” he asked. The tasks he listed for the cheaper option were ordinary ones: “summarizing an email, examining a contract, answering a customer call, composing an email”.
In the same answer, Krishna said running open-weight models well takes engineers who tune GPU kernels, plan the network and cache results, and that the gap in those skills “is probably still there, except for the most sophisticated enterprise”. Without them, buyers go back to the frontier model. “I got it that the answer is four times more expensive, but it’s the easy answer,” he said.
On IBM’s figures, open models now score close to frontier ones on quality. What AI costs a mid-market company now turns on who runs the cheaper models and what they charge for it, and that operating layer is what IBM and its rivals are lining up to sell.
How the benchmark gap closed
In late 2024, Krishna said, a broad benchmark might score the top frontier model at 70 and an open model at “a 20 or a 30”. By late 2025 the gap was 70 to 50, and IBM was “very comfortable that we’d get this to probably 100 for the top and 90 for the alternate model”.
Those are IBM’s own assessments, not a published benchmark, and IBM has a stake in them. It sells Red Hat’s hybrid cloud software, Spyre accelerator cards for its mainframes and Bob, a watsonx tool for AI-driven software development that now runs on clients’ own infrastructure. Its prepared remarks also promoted llm-d, an open-source inference project developed with Red Hat and Google, which IBM says lets clients run large models at five to 10 times lower cost on existing GPUs.
In the quarter, Red Hat revenue grew 11%, and growth in OpenShift annual recurring revenue accelerated to more than 30%, which IBM tied to organizations moving AI applications and agents into production. Total revenue rose 5%, or 6% at constant currency.
What two or three racks means
Krishna’s sizing was for “an average large enterprise”, which he said could “get going with maybe two or three racks”. He called that “not a huge amount of infrastructure”. By his own account, the skills to run it are missing everywhere except at the most sophisticated enterprises, and a mid-market IT department is further from that description than the large enterprise he was sizing for.
Krishna said vendors would “produce much more sort of easy button software” for the cheaper models. In his answer on sovereign AI, he described open-weight models as ones buyers have “the permission and the IP rights to run” on their own infrastructure or on private clouds, where the enterprise controls what happens to the logs and data.
A token price of 10–25% of the frontier rate is a saving of 75–90% before anyone is paid to operate the model. How much of it reaches a company that rents that operation depends on the provider’s margin, which Krishna’s arithmetic did not include.
Where cost and control meet
IBM’s prepared remarks framed AI buying around two questions from clients: “what will it cost, and who controls it?” On the call, Krishna answered the second through sovereignty. Using a large public model, he said, leaves “traces” in the provider’s logs that give “some indication” of what it is used for and of some of the data involved.
He described the chief executive of a large bank outside the US who planned to experiment with frontier models but to run its own work so that “nobody can take any of the underlying data or underlying logs”. Krishna expects that preference to become “a tailwind” for infrastructure and semiconductor companies and for firms such as IBM that deploy AI privately.
For contract review, call handling and email, the two questions now give the same answer on IBM’s numbers: the open model is cheaper, and the data stays in an environment the company or its provider controls. Krishna also told the call that “a lot of people are underplaying how much work it is to integrate AI into your workflows”.
IBM’s pricing case uses the low end of Krishna’s 10–25% range. For companies without their own kernel engineers, the number that settles the choice is one Krishna did not give: what a provider charges to run the cheaper model for them, and whether that still undercuts the frontier model’s easy answer.
Get The VETTDD BriefingThe week in B2B technology, every week.
Subscribe freeSources
- IBM, “IBM 3Q 2026 Earnings Conference Call Transcript”, webcast transcript, 21 October 2026. https://www.ibm.com/downloads/documents/us-en/17f55bd310d5fdd0
- IBM, third-quarter 2026 prepared remarks, 21 October 2026. https://www.ibm.com/downloads/documents/us-en/17f55bddaac4eb80
- IBM, “IBM Releases Third-Quarter Results”, press release, 21 October 2026. https://newsroom.ibm.com/2026-10-21-IBM-RELEASES-THIRD-QUARTER-RESULTS
- The Register, “IBM CEO says open weight models are now irresistibly good and cheap on-prem”, 22 October 2026. https://www.theregister.com/systems/2026/10/22/ibm-ceo-says-open-weight-models-are-now-irresistibly-good-and-cheap-on-prem/5304640
Editor
The VETTDD editorial desk. Interviews, analysis, columns and news briefs on the decisions shaping B2B technology.
More from Editor
The week in B2B technology, in five minutes
Every week: the interview, the briefs that matter and one view from the editor. Free.